Why we started writing KubeVela definitions in Go

· 30 min read
Vaibhav Agrawal
KubeVela Contributor

If you have written an X-Definition, you have written CUE. Components, traits, policies, and workflow steps all carry their logic as a CUE template, and that template is where your platform's real behaviour lives. It is what the KubeVela controller evaluates every time an Application renders. Change a definition and you change how every app on the platform gets delivered.

Which makes the authoring experience matter more than it first appears. A definition is some of the most consequential code a platform team writes, and it is written in a language most platform teams touch nowhere else. We felt that every time we added one, and eventually went looking for a different way to write them.

As of v1.11.0, KubeVela ships one. Defkit is a Go SDK for authoring X-Definitions: you write Go, and it compiles to CUE.

LFX Mentorship: Building Memory-Bounded LRU Cache for KubeVela's Native Helm Provider

· 10 min read
Kavish Parikh
KubeVela Contributor

Hello, I'm Kavish Parikh. In this blog, I want to share my experience participating as an LFX Mentee under the KubeVela project.

My mentorship project, LRU Cache Eviction for the Native Helm Provider, focused on improving how KubeVela caches Helm charts during application reconciliation. Over the course of the mentorship, I worked on designing a memory-bounded LRU cache, integrating it into KubeVela, and making the cache reusable across different components of the project.

Modeling AI inference with KubeVela and OAM

· 14 min read
Ayush Kumar
KubeVela Contributor

AI product work used to be dominated by training: big clusters, rare model releases, and a one-time capital bill. That center of gravity has moved. Once a model ships, the lasting cost is inference: every chat turn, every tool call, every agent loop that keeps the meters running.

Industry analyses put the AI inference market on the order of $100B+ in 2025, with projections toward roughly $255B by 2030 (SoftwareSeni overview of Grand View / MarketsandMarkets figures; directional, not exact). Stanford HAI’s AI Index 2025 documents a collapse in unit price for GPT-3.5-class quality inference, from about $20 per million tokens to roughly $0.07 over a two-year window, while total spend still rose because cheaper tokens unlock more traffic (also summarized in Telnyx’s training vs inference note). Over a model’s lifetime, infrastructure write-ups commonly put inference at ~80–90% of compute dollars versus a minority share for training (Introl on inference vs training economics).

That shift shows up as an engineering problem. Inference is no longer “call an API.” Self-hosted stacks need model selection, runtime choice (Ollama, vLLM, Triton), autoscaling, placement, observability, and increasingly inference-aware routing. On Kubernetes, the Gateway API Inference Extension standardizes model-aware pools and endpoint picking, and llm-d sits above model servers for cache-aware scheduling and disaggregated serving.

What still needs a clean answer is the application delivery layer: how platform teams expose a stable contract to product teams without every service owning a private copy of Deployment YAML, env vars, and tribal knowledge about backends.

KubeVela and the Open Application Model (OAM) were built for exactly that kind of packaging problem. Components describe what runs. Traits attach reusable capabilities. Policies and workflows handle placement, overrides, and delivery. This post applies that model to AI inference in a local-first proof of concept: an OpenAI-compatible facade as a Component, operational behaviors as Traits, multi-env promotion with built-in policies, and a deliberate seam toward llm-d without requiring a full GPU stack on day one.

The result is encouraging. KubeVela is a natural fit for composing and shipping inference apps while specialized projects own the heavy serving path. The sections below cover the design, the YAML, the measured results, and how the pieces fit together.

KubeVela ResourceTracker Pattern: How Self-Healing Works Without Watching Every Resource

· 27 min read
Vishal Kumar
KubeVela Contributor

Every Kubernetes operator answers the same question whenever a child resource changes: "which parent should I reconcile?" The usual answer is controller-runtime's .Owns() helper, which registers an Informer per child type, caches them, and reads the OwnerReference on each child to find its parent. That's fine when you know your child types up front. It stops being fine when your operator is a platform engine and users keep inventing new resource types.

KubeVela takes a different route. The Application controller doesn't watch Pods, Deployments, or Services at all. It watches three KubeVela CRDs and keeps a separate record — the ResourceTracker — that lists everything an Application is supposed to have created. This post covers why the design exists, how self-healing works without event-driven watches on children, what you can tune, and how the approach compares to plain client-go and controller-runtime.

State of KubeVela 2025: A Year of Maturity, Community, and Looking Ahead

· 8 min read

As we close out 2025, we want to take a moment to reflect on what has been a transformative year for KubeVela. From major releases to community growth, from enterprise adoption to exciting new features on the horizon—this year has reinforced our belief that making application delivery enjoyable is not just a tagline, but a mission worth pursuing.

KubeVela 1.10.4 Now Available

· 6 min read
Brian Kane
KubeVela Team

Hello community! 👋

This is the first blog post in a while but we are excited to reinvigorate the community and keep developers and users up to date with all things KubeVela. The team is committed to providing regular updates, news and information about upcoming events and features.

We recently released the latest v1.10.4 which includes a host of useful features to improve the maintainability of Applications deployed with Kubevela. This blog will provide a quick overview of the features and how you can get started with utilising them in your KubeVela setup.

While v1.10.4 follows semantic versioning as a patch release, we're excited to deliver several new opt-in features alongside the usual bug fixes and improvements.

These features are disabled by default (where applicable) to maintain backward compatibility, allowing users to adopt them at their own pace.

LFX Mentorship: Meeting with the KubeVela Community in Open Source

· 10 min read
Junyu Liu
KubeVela Contributor

Hello, I am Junyu Liu (GitHub: iyear), currently a sophomore majoring in software engineering. In this blog post, I will share my experiences as a Linux Foundation Mentorship mentee: from applying for the project to becoming part of the community.

In the spring of 2023, I was accepted as a CNCF student under the KubeVela project through LFX Mentorship. In this project, I am responsible for developing a CUE code and documentation generator based on Golang from scratch, laying the foundation for the infrastructure part of KubeVela's future extensibility.

PromptOps in Application Delivery: Empowering Your Workflow with ChatGPT

· 10 min read
Fog Dong
KubeVela Team

ChatGPT is taking the tech industry by storm, thanks to its unparalleled natural language processing capabilities. As a powerful AI language model, it has the ability to understand and generate human-like responses, revolutionizing communication in various industries. From streamlining customer service chatbots to enabling seamless language translation tools, ChatGPT has already proved its mettle in creating innovative solutions that improve efficiency and user experience.

Now the question is, can we leverage ChatGPT to transform the way we deliver applications? With the integration of ChatGPT into DevOps workflows, we are witnessing the possible emergence of a new era of automation called PromptOps. This advancement in AIOps technology is revolutionizing the way businesses operate, allowing for faster and more efficient application delivery.

In this article, we will explore how to integrate ChatGPT into your DevOps workflow to deliver applications.

Interpreting KubeVela 1.7: Taking Over Your Existing Workloads

· 16 min read
Jianbo Sun
KubeVela Team

The KubeVela 1.7 version has been officially released for some time, during which KubeVela has been officially promoted to a CNCF incubation project, marking a new milestone. KubeVela 1.7 itself is also a turning point because KubeVela has been focusing on the design of an extensible system from the beginning, and the demand for the core functionality of controllers has gradually converged, freeing up more resources to focus on user experience, ease of use, and performance. In this article, we will focus on highlighting the prominent features of version 1.7, such as workload takeover and performance optimization.

KubeVela brings software delivery control plane capabilities to CNCF Incubator

· 7 min read
CNCF
CNCF

Originally post in CNCF.

The CNCF Technical Oversight Committee (TOC) has voted to accept KubeVela as a CNCF incubating project.

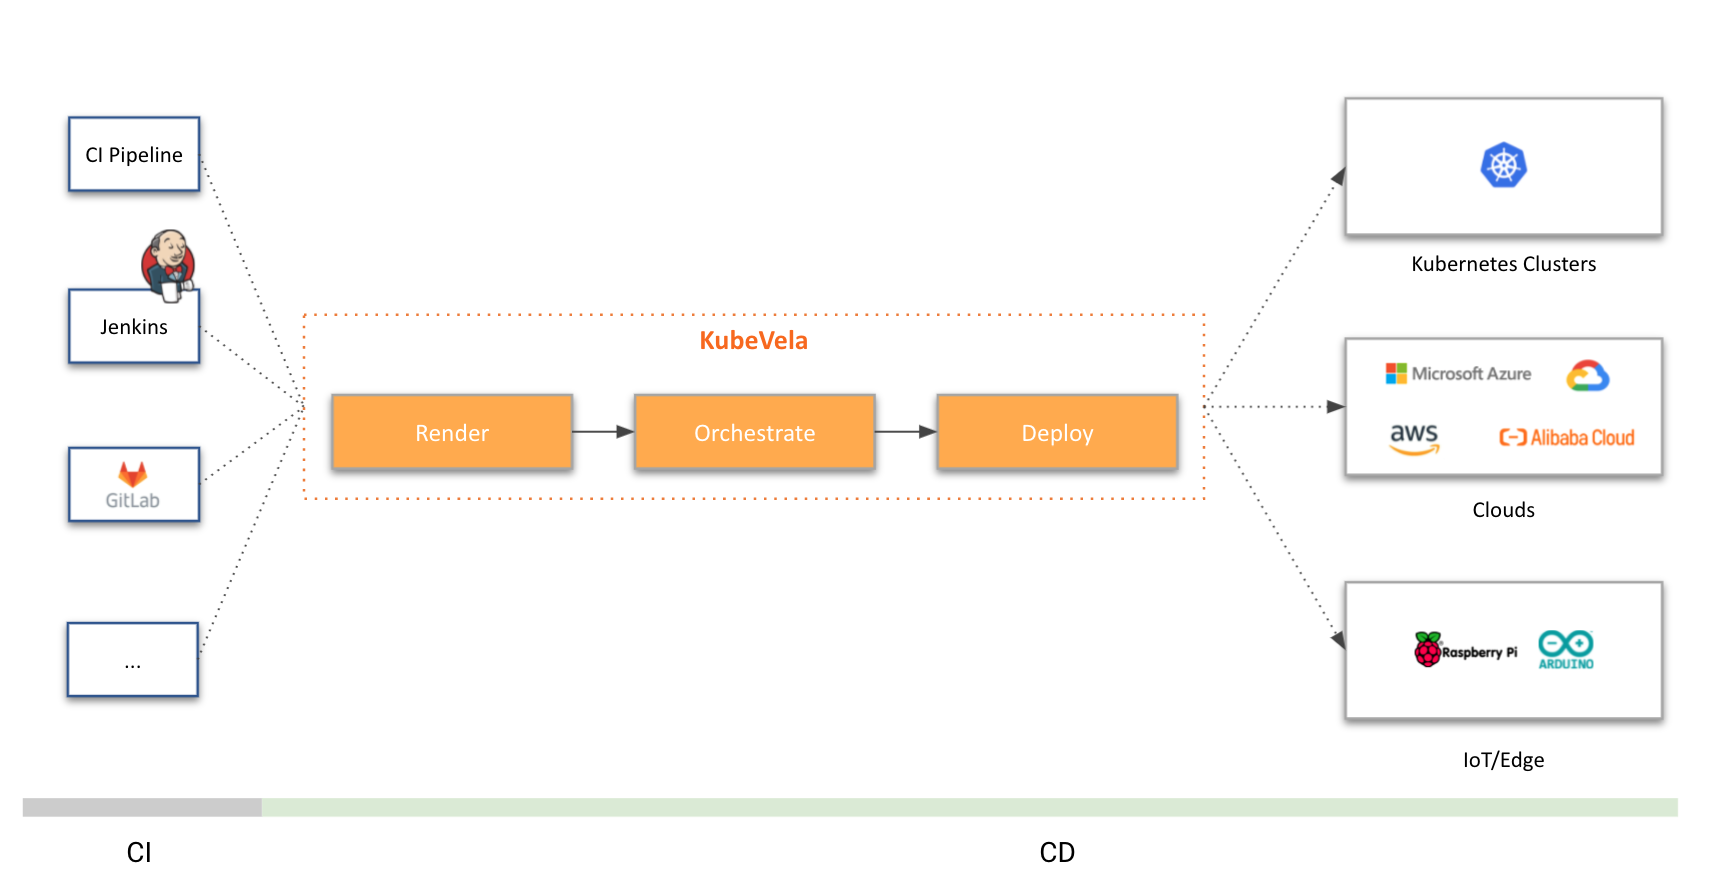
KubeVela is an application delivery engine built with the Kubernetes control plane that makes deploying and operating applications across hybrid and multi-cloud environments easier, faster, and more reliable. KubeVela can orchestrate, deploy, and operate application components and cloud resources with a workflow-based application delivery model. The application delivery abstraction of KubeVela is powered by the Open Application Model (OAM).

image.png